NeurIPS 2026

Learning Where and What to Restore
for Composite Image Restoration

CART: Composite-Adaptive Routing and Task Conditioning

*Equal contribution   †Corresponding authors

Formerly titled Cat-AIR: Content and Task-Aware All-in-One Image Restoration (arXiv v1).

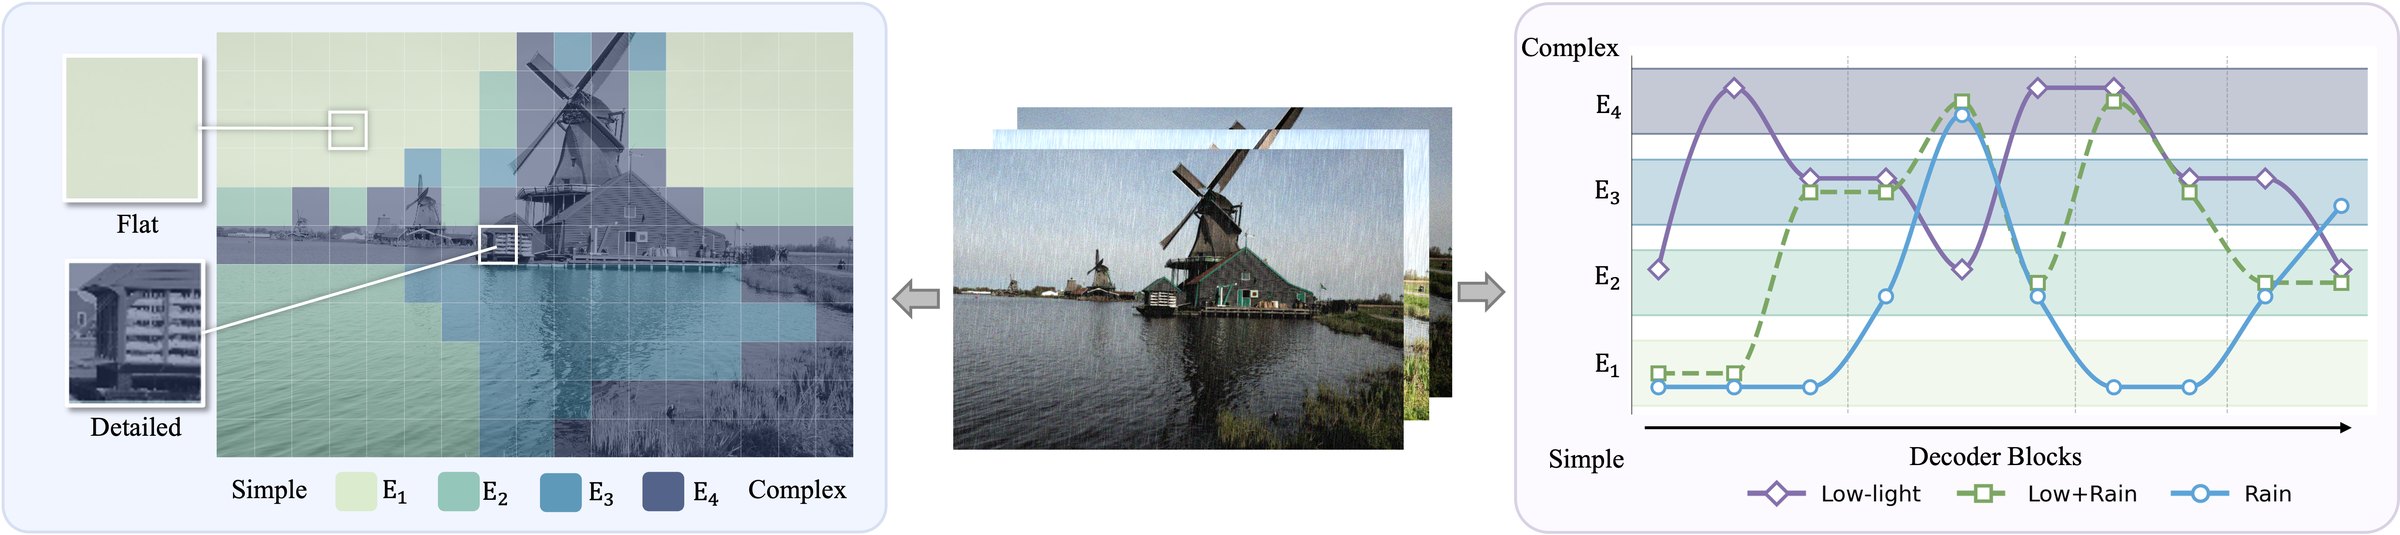
Left: a windmill image split into patches, each colored by the expert it is routed to, from E1 for flat sky to E4 for detailed structures. Right: the expert chosen at each decoder block for low-light, rain, and low-light plus rain inputs; the composite path blends the two single-degradation paths.
Composite restoration needs to decide where and what to restore. Left (where): every patch is routed to one of four capacity-graded experts, from E1 (simple) to E4 (complex); flat regions use lightweight experts and detailed regions use high-capacity ones. Right (what): the expert chosen at each decoder block traces a path; each degradation follows its own trajectory, and the composite Low+Rain path (dashed) blends its constituents.

Average PSNR on CDD-11

29.95 dB

+0.90 dB vs. MoCE-IR

CDD-11 conditions ranked best

10 of 11

in PSNR · all 11 in SSIM

Compute per 128×128 input

19.47 GFLOPs

−26% vs. MoCE-IR

Runtime on one A5000

32.11 ms

Fastest of all compared methods

Abstract

Abstract

Real-world degraded images often contain multiple co-occurring degradation types, making composite image restoration fundamentally different from the single-degradation setting assumed by most existing all-in-one methods. These methods typically apply uniform spatial computation and single-label task conditioning, limiting both spatial adaptivity and explicit modeling of degradation mixtures. We propose CART (Composite-Adaptive Routing and Task Conditioning), a unified framework that jointly decides where to spend computation and what degradation cues should guide restoration: a spatial mixer routes patches to graded-capacity experts by local restoration difficulty, and a channel mixer routes each image through degradation-specific experts, conditioned on the global task feature with multi-hot classification supervision. Empirically, CART achieves state-of-the-art performance for composite degradation restoration on CDD-11 and delivers the best results to date on the conventional 3-task and 5-task all-in-one benchmarks.

Motivation

Degradations rarely come alone

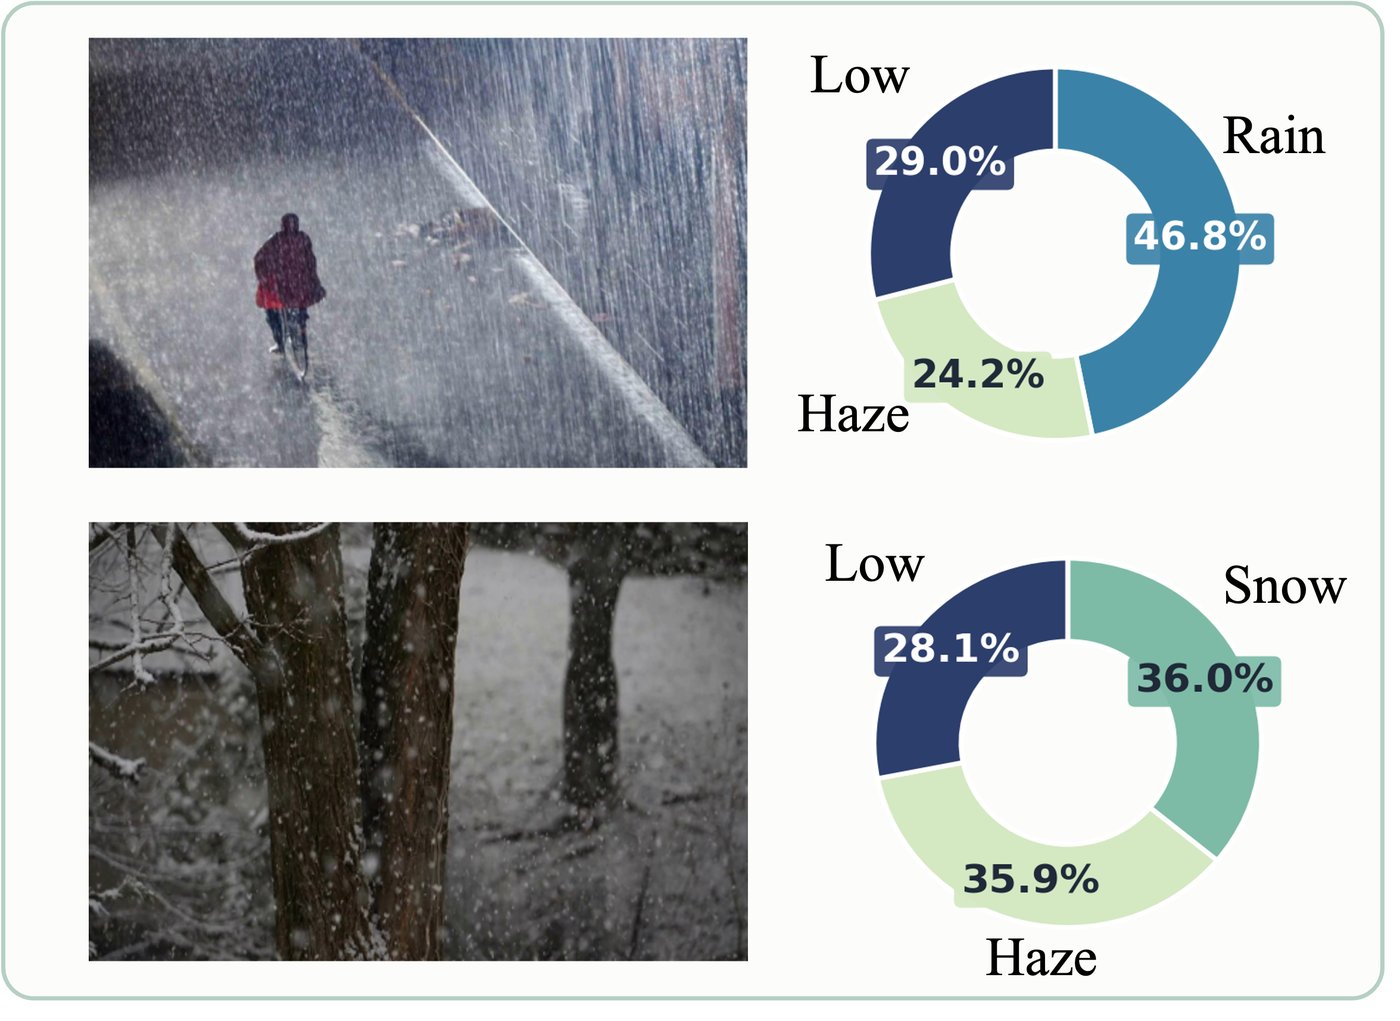
In the wild, rain, snow, haze and low light co-occur in varying proportions rather than as one dominant corruption. Restoring such composite degradations breaks two assumptions built into most all-in-one models:

  • Difficulty varies across the image. A uniform sky needs little computation, while dense edges under mixed degradations need much more. Yet most architectures spend the same computation on every region.
  • The degradation label is a set. M elemental types give 2M − 1 possible mixtures, and a single image-level prompt or label cannot say that several degradations are present at once.
Two real-world photos with donut charts. A person walking in heavy rain is estimated as 46.8% rain, 29.0% low-light and 24.2% haze; a snowy forest as 36.0% snow, 35.9% haze and 28.1% low-light.
Real-world samples contain several co-occurring degradations. The proportions are predicted by CART’s channel mixer.

Method

Two routers: one for where, one for what

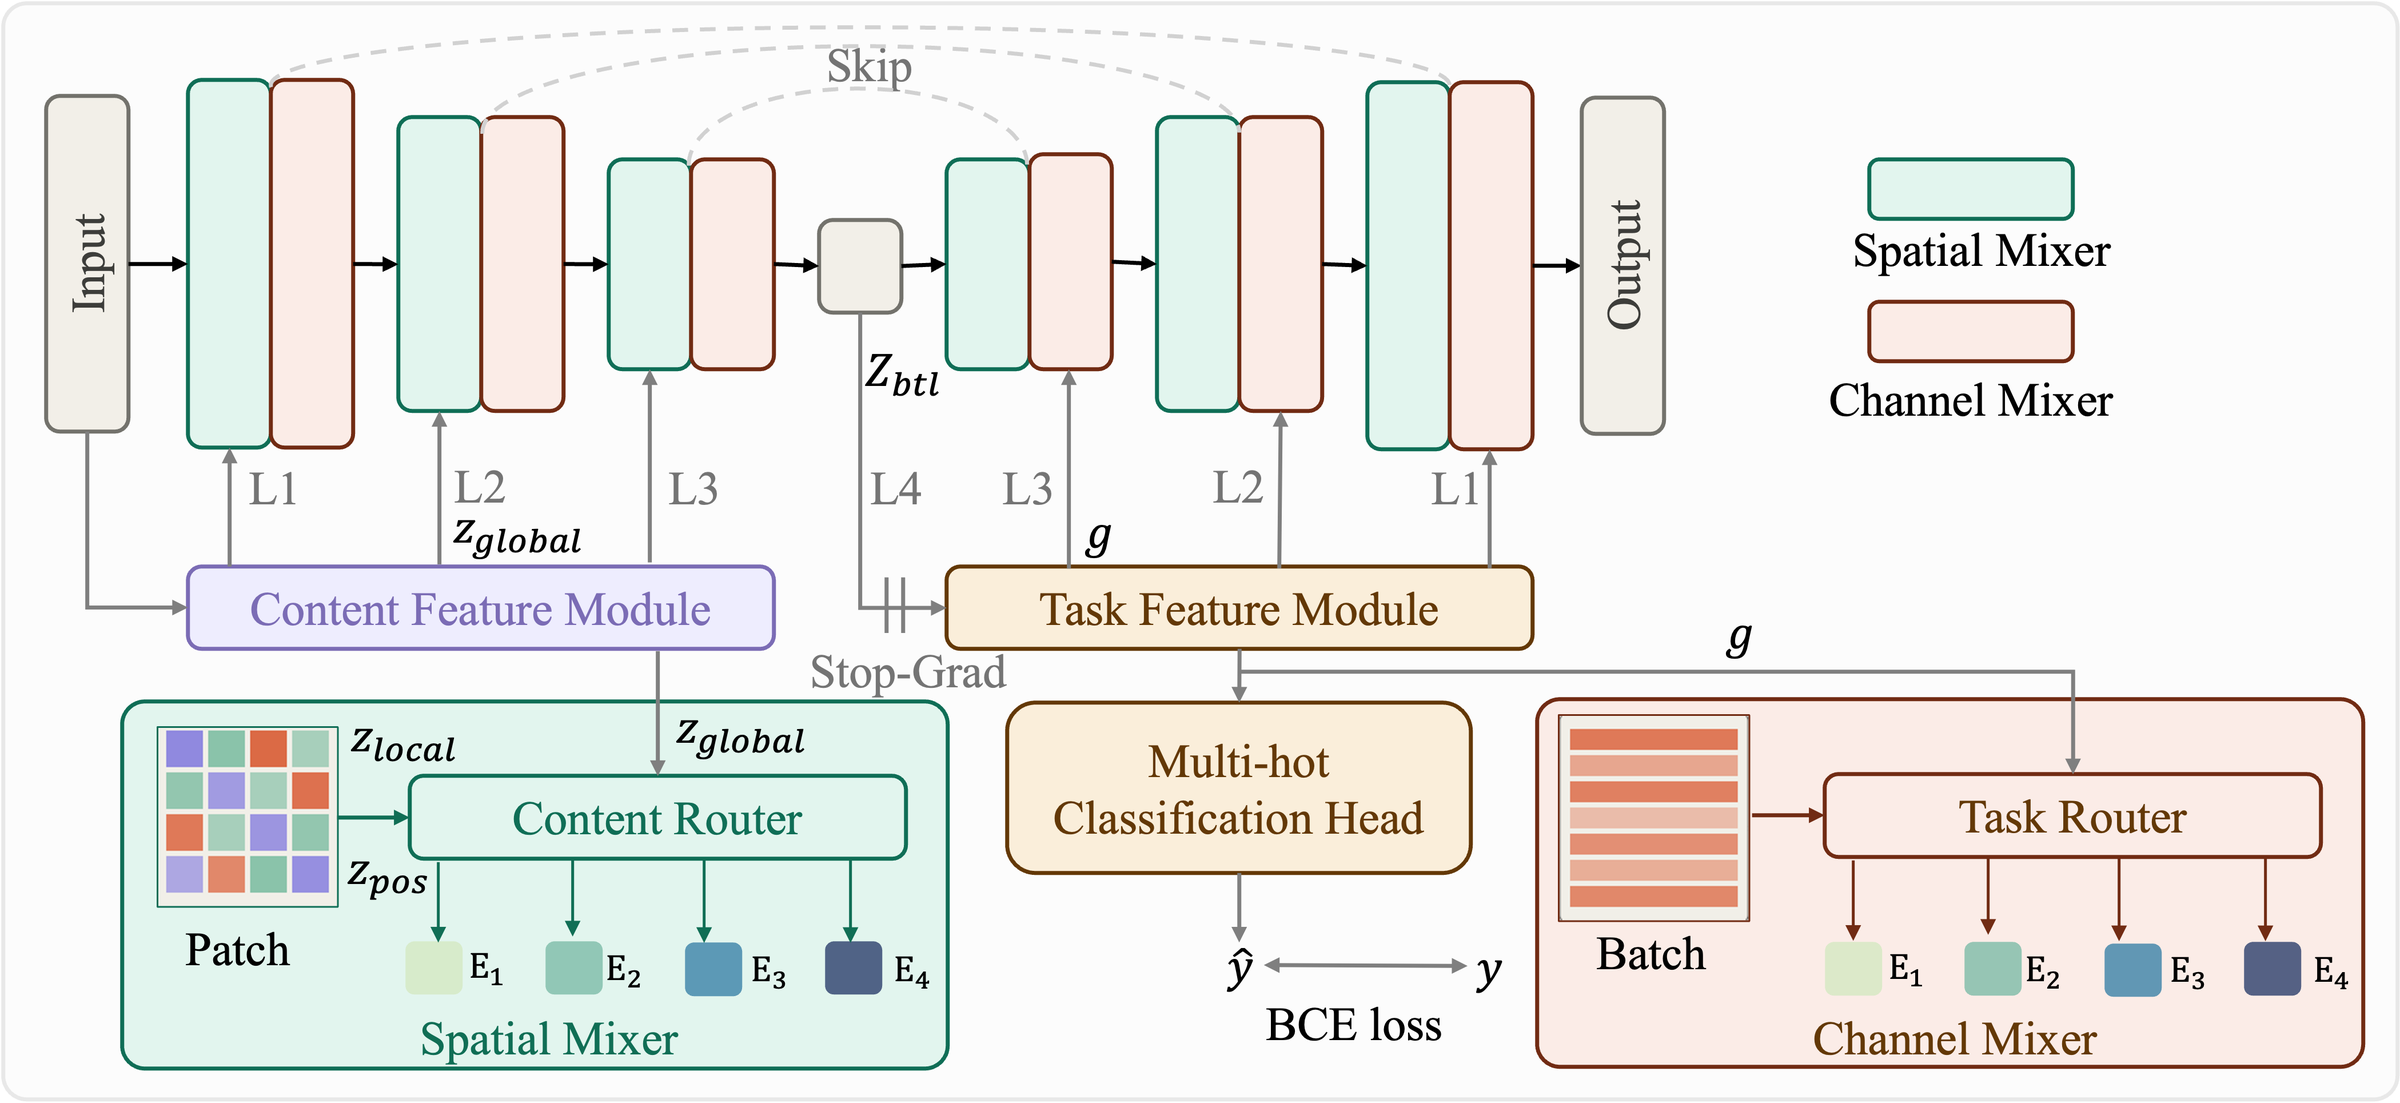
CART is a four-level U-Net whose blocks alternate a spatial mixer, which decides where to spend computation, and a channel mixer, which decides what degradation cues guide restoration. Each mixer chooses among K = 4 experts of graded capacity.

CART architecture: a U-Net encoder-decoder of alternating spatial and channel mixer blocks. A content feature module feeds a content router that assigns patches to spatial experts E1 to E4. A task feature module at the bottleneck, behind a stop-gradient, feeds a multi-hot classification head trained with BCE loss and a task router that assigns each image to channel experts E1 to E4.
Overview of CART. The spatial mixer routes each patch to one of K experts of graded capacity by local restoration difficulty. A task feature module extracts a global task feature g at the bottleneck, supervised with multi-hot degradation classification; the channel mixer uses it to route each image through one of K channel-attention experts in the decoder.

Where to spend computation

Spatial mixer

Each block holds four windowed self-attention experts with the same structure but growing hidden width. A lightweight content router sees each patch’s local embedding, a global content descriptor taken from first-level encoder features (which still keep fine detail), and the patch position, then sends the patch to exactly one expert.

Flat regions go to light experts; textured, heavily degraded regions get full capacity.
What degradation cues to use

Channel mixer

A task feature module at the bottleneck extracts a global task feature g, supervised by multi-hot classification: one binary output per elemental degradation instead of one class per mixture. A stop-gradient keeps this objective out of the shared encoder. At every decoder block, a task router uses g to send the whole image through one of four channel-attention experts.

Different degradations activate their own parameters, with no task label needed at inference.

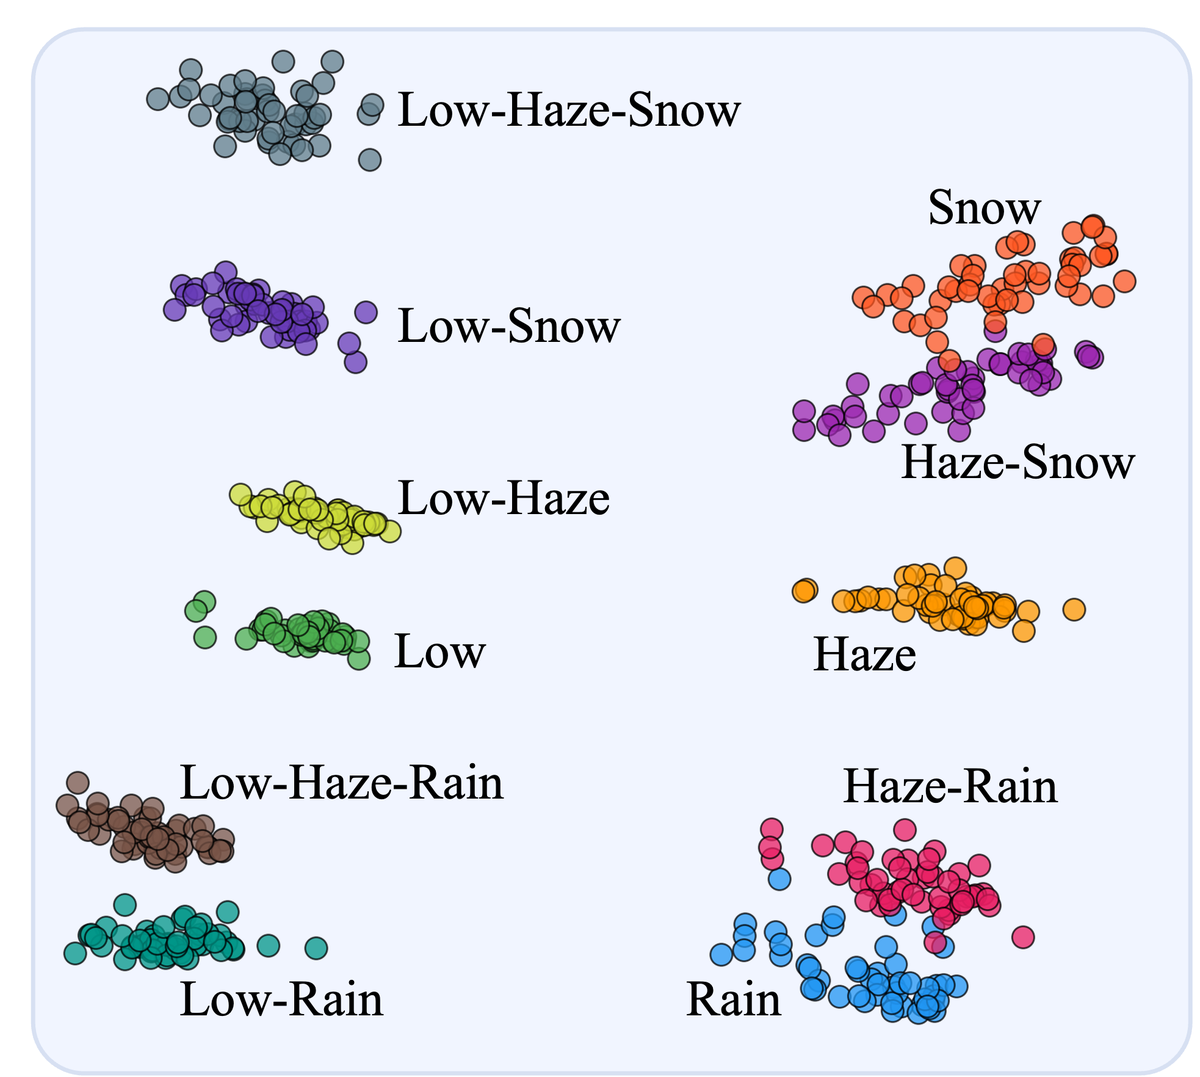
PCA scatter of task features on CDD-11. Clusters for Low, Haze, Rain and Snow are well separated, and composite clusters such as Haze-Rain and Low-Haze sit between their single-degradation constituents.
PCA of the task feature g across CDD-11 conditions.

A compositional task representation

Treating every mixture as its own class discards the fact that haze + rain is related to both haze and rain, and the number of classes grows as 2M − 1. Multi-hot supervision keeps that structure. In the learned task feature, clusters for different degradations are well separated, and each composite cluster lies between its single-degradation constituents. Parameter sharing across related tasks thus emerges from the learned representation rather than from a fixed architectural choice.

Results

State of the art on composite and standard benchmarks

One unified model per benchmark. The main evaluation is CDD-11, which covers single, double and triple combinations of low-light (L), haze (H), rain (R) and snow (S). To check that the design still helps when only one degradation is present, CART is also evaluated on the conventional 3-task and 5-task all-in-one benchmarks.

All methods are trained from scratch on CDD-11; Avg is the macro-average over the 11 conditions. CART ranks best on 10 of 11 conditions in PSNR and on all 11 in SSIM. Its lead grows on mixtures, e.g. +1.68 dB on H+R and +2.09 dB on H+S over MoCE-IR.

SingleTwo degradationsThree
MethodLHRSL+HL+RL+SH+RH+SL+H+RL+H+SAvg
AirNet24.83.77824.21.95126.55.89126.79.91923.23.77922.82.71023.29.72322.21.86823.29.90121.80.70822.24.72523.75.814
PromptIR26.32.80526.10.96931.56.94631.53.96024.49.78925.05.77124.51.76124.54.92423.70.92523.74.75223.33.74725.90.850
WGWSNet24.39.77427.90.98233.15.96434.43.97324.27.80025.06.77224.60.76527.23.95527.65.96023.90.77223.97.77126.96.863
WeatherDiff23.58.76321.99.90424.85.88524.80.88821.83.75622.69.73022.12.70721.25.86821.99.86821.23.71621.04.69822.49.799
OneRestore26.48.82632.52.99033.40.96434.31.97325.79.82225.58.79925.19.78929.99.95730.21.96424.78.78824.90.79128.47.878
MoCE-IR27.26.82432.66.99034.31.97035.91.98026.24.81726.25.80026.04.79329.93.96430.19.97025.41.78925.39.79029.05.881
CART ours27.05.83634.52.99435.46.97637.54.98326.40.83626.40.81926.33.81431.61.97432.28.97825.93.81325.96.81429.95.894

Each cell shows PSNR (dB) above SSIM. Bold is the best value in its column.

Visual comparison

See the difference on CDD-11

Drag the divider to compare CART (right) with the input, two strong baselines, or the ground truth (left).

CART restoration of the haze scene Degraded input of the haze scene Input CART (ours)

Scene

Compare CART with

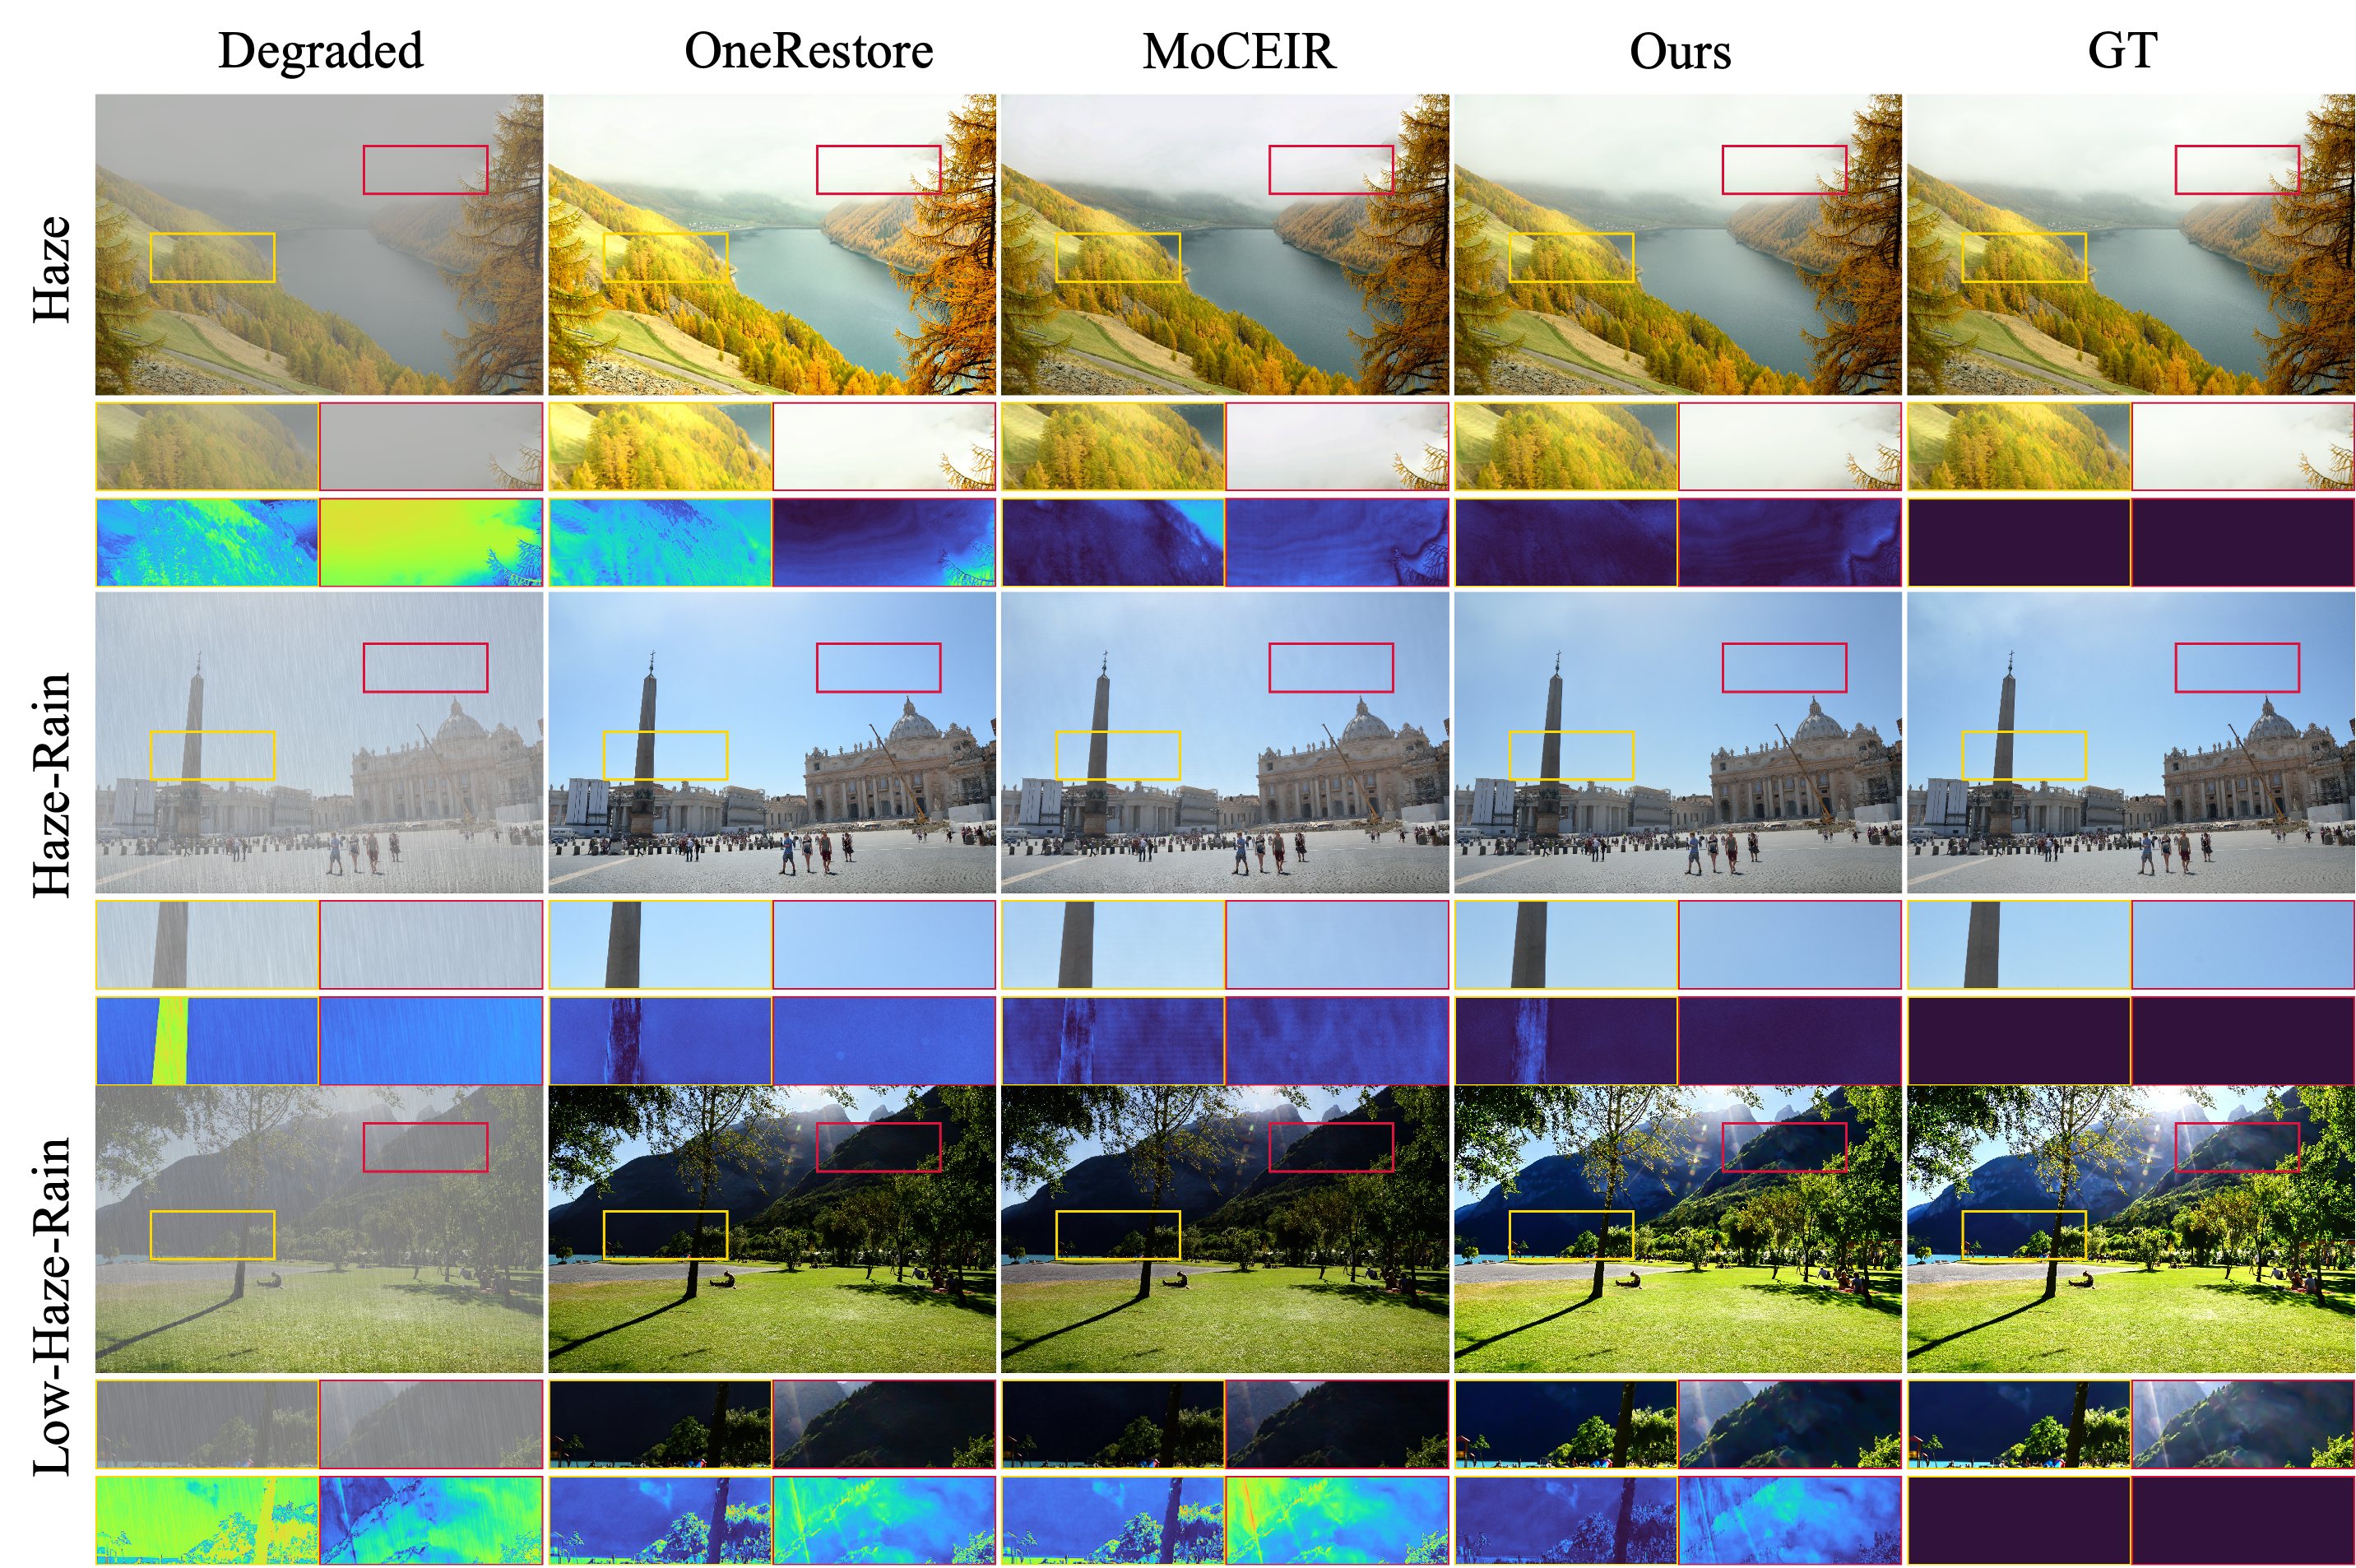
On haze, OneRestore introduces a color cast and MoCE-IR leaves residual haze, while CART preserves natural tones.

Grid of results on three CDD-11 scenes (haze, haze plus rain, low-light plus haze plus rain) for the degraded input, OneRestore, MoCE-IR, CART and ground truth, each with zoomed crops and per-pixel error maps.
Degraded input, OneRestore, MoCE-IR, CART and ground truth on three CDD-11 cases. Under each image: zoomed regions, then the per-pixel error map to the ground truth (darker means a smaller residual). Click to open at full resolution.

Analysis

Do the routers learn where and what?

Two probes on the CDD-11 test set check whether each mixer does the job it was designed for.

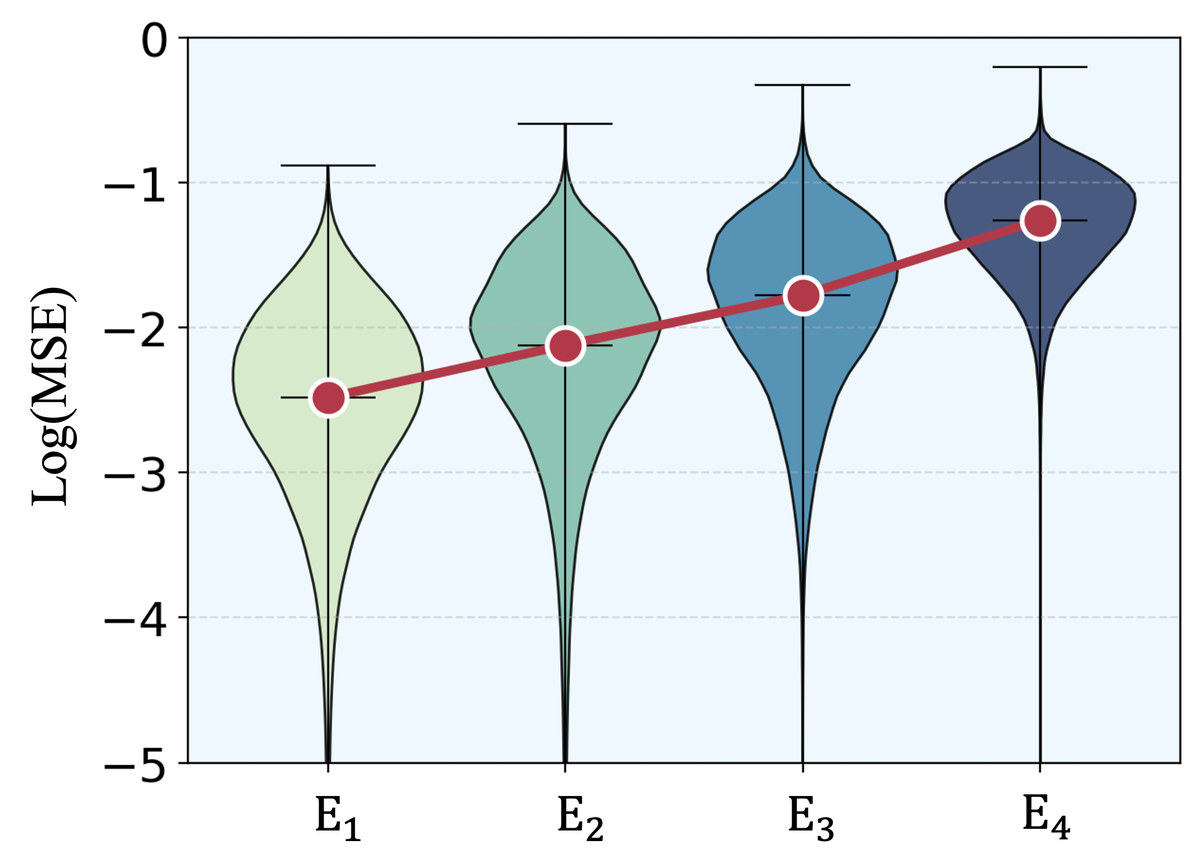
Violin plots of per-patch log MSE for patches routed to spatial experts E1 to E4; the mean rises steadily from about −2.5 at E1 to about −1.3 at E4.
Per-patch log MSE, grouped by the spatial expert that processed the patch.

Spatial routing tracks patch difficulty

Patch difficulty is measured as the log MSE between a degraded patch and its target. Grouped by assigned expert, the mean difficulty rises monotonically from E1 to E4: easy patches concentrate at the lightweight E1, and heavily corrupted patches reach the full-capacity E4. The router learns to match patch difficulty to expert capacity without any direct supervision on its decisions.

Channel routing reflects compositional identity

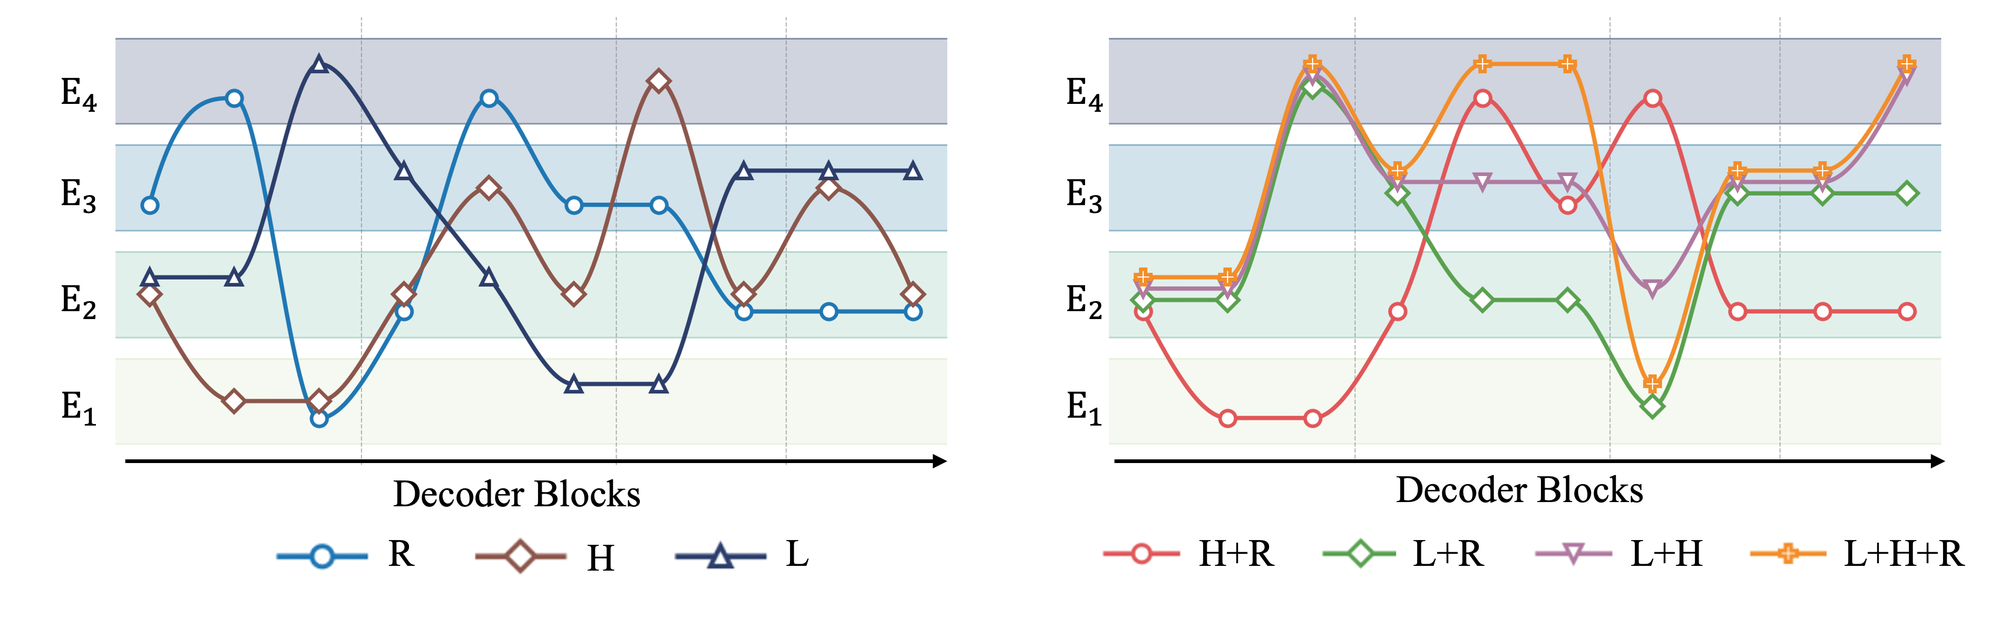
Each degradation is summarized by its most frequently selected expert at every channel-mixer block. Single degradations follow well-separated decoder paths. Composite inputs trace paths that largely overlap with their constituents; haze + rain, for example, blends the routes chosen for haze and for rain. The model reuses elemental structure and recombines it at inference.

Line charts of the most frequent channel expert at each decoder block. Left: rain, haze and low-light follow distinct paths. Right: haze plus rain, low plus rain, low plus haze and low plus haze plus rain follow paths that overlap with their constituents.
Most frequent channel expert at each decoder block: single degradations (left) and composites (right).

Efficiency

Best quality at the lowest compute

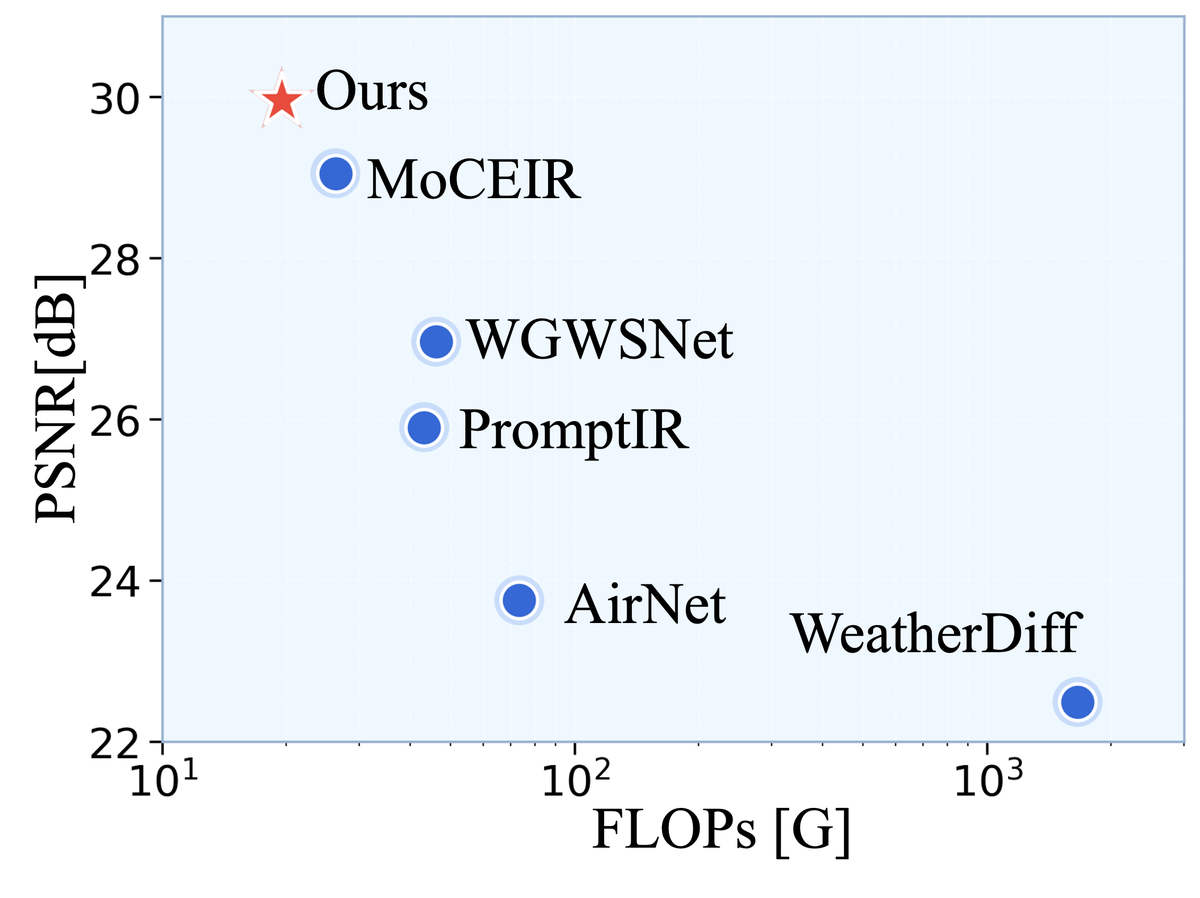
Scatter plot of average PSNR on CDD-11 against FLOPs on a log scale. CART sits in the upper-left corner at about 30 dB and under 20 GFLOPs, above MoCE-IR, WGWSNet, PromptIR, AirNet and WeatherDiff.
Average PSNR on CDD-11 against FLOPs (log scale).
MethodParams (M)FLOPs (G)Memory (MB)Time (ms)
AirNet8.9373.4212238.44
PromptIR35.5943.1828835.33
WGWS-Net19.7746.1511360.71
WeatherDiff85.611658.45431383.75
MoCE-IR25.3526.2916145.46
CART ours32.5819.4719532.11

Measured on 1×3×128×128 inputs at batch size 1 on a single A5000 GPU in FP32. Bold is the lowest value in its column.

CART needs 19.47 GFLOPs, 26% less than MoCE-IR, and runs fastest at 32.11 ms. Because the mixture-of-experts design stores all K experts while activating one per input, it has more parameters and higher peak memory than MoCE-IR. We view this as a worthwhile trade, since compute and latency dominate at inference.

Citation

BibTeX

@inproceedings{jiang2026cart,
  title     = {Learning Where and What to Restore for Composite Image Restoration},
  author    = {Jiang, Jiachen and Ding, Tianyu and Zhang, Ke and Zhou, Jinxin and
               Chen, Tianyi and Zharkov, Ilya and Zhu, Zhihui and Liang, Luming},
  booktitle = {Advances in Neural Information Processing Systems (NeurIPS)},
  year      = {2026}
}

Earlier version: Cat-AIR

This paper first appeared in March 2025 as Cat-AIR: Content and Task-Aware All-in-One Image Restoration (arXiv v1). The NeurIPS camera-ready version renames the method to CART and extends it to composite degradations. Resources released with the earlier version: